

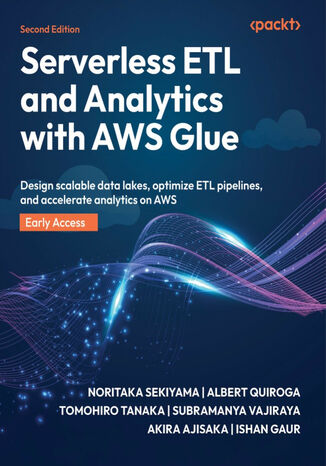
Serverless ETL and Analytics with AWS Glue. Design scalable data lakes, optimize ETL pipelines, and accelerate analytics on AWS - Second Edition Noritaka Sekiyama, Albert Quiroga, Tomohiro Tanaka, Subramanya Vajiraya, Akira Ajisaka, Ishan Gaur
 angielski
- Autorzy:
- Noritaka Sekiyama, Albert Quiroga, Tomohiro Tanaka, Subramanya Vajiraya, Akira Ajisaka, Ishan Gaur
- Wydawnictwo:
- Packt Publishing
- Ocena:
- Stron:
- 532
- Dostępne formaty:
-
PDFePub
Opis
książki
:
Serverless ETL and Analytics with AWS Glue. Design scalable data lakes, optimize ETL pipelines, and accelerate analytics on AWS - Second Edition
This book guides you from modern data management and core AWS Glue features through ingestion from files, streams, SaaS applications, and JDBC sources, preparation, storage layout, metadata, security, sharing, and pipeline operations. Console walkthroughs and runnable examples show how to manage schemas and lineage in AWS Glue Data Catalog, apply AWS Lake Formation access controls, monitor workloads, tune Spark jobs, troubleshoot failures, and manage development with AWS CDK, Docker, and CI/CD. You will also examine analytics, machine learning and generative AI integrations, real-world data lake scenarios, and cost optimization. Learn how Apache Iceberg, Apache Hudi, and Delta Lake add transactions, schema evolution, and efficient data management to data lakes.
By the end, you will be able to design, build, operate, and continuously improve a serverless data platform that fits your organization's scale, structure, and priorities.
Wybrane bestsellery
-
 Serverless ETL and Analytics with AWS Glue acts a single resource, providing a holistic view of the various features of Glue, and teaches you how to use each one of them. This book helps you to understand the entire process of building data lakes using AWS Glue and other AWS services.
-
-
ebook
(29,90 zł najniższa cena z 30 dni)
233.10 zł
259.00 zł (-10%) -
-
 MLOps (ang. machine learning operations) to jedna z najszybciej rozwijających się dziedzin IT, łącząca uczenie maszynowe z praktykami DevOps. W erze cyfrowej transformacji, gdy organizacje coraz częściej wdrażają modele AI w środowiskach produkcyjnych, potrzeba skutecznego zarządzania cyklem życia modeli uczenia maszynowego staje się kluczowa. Książka MLOps dla biznesu odpowiada na rosnące zapotrzebowanie rynku na praktyczne przewodniki po tej złożonej tematyce, oferując kompleksowe podejście do skalowania rozwiązań AI w przedsiębiorstwach.
-
książka
-
ebook
(41,40 zł najniższa cena z 30 dni)
41.40 zł
69.00 zł (-40%) -
-
 Aplikacje typu cloud-native, na których budowie i implementacji skupia się ta książka, są tworzone specjalnie dla środowisk chmurowych. Tego typu rozwiązanie, korzystające z elastyczności chmury, opiera się na architekturze mikroserwisów, konteneryzacji, interfejsach API i automatyzacji. Dzięki temu jest szybkie we wdrażaniu, odporne na awarie i łatwe do rozbudowy.
-
książka
-
ebook
(40,20 zł najniższa cena z 30 dni)
42.88 zł
67.00 zł (-36%) -
-
 Ten obszerny przewodnik pokaże Ci, jak stosować najlepsze praktyki w pracy z LLM. Znajdziesz tu omówienie kluczowych koncepcji, praktyczne techniki i porady ekspertów z zakresu inżynierii danych, dostrajania i oceny modeli, optymalizacji wnioskowania, a także budowania skalowalnych potoków przetwarzania. Krok po kroku prześledzisz, jak zrealizować konkretny produkt, integrując różne aspekty inżynierii LLM i metodologię MLOps. Dowiesz się, jak zbierać i przygotowywać dane, dostrajać modele do specyficznych zastosowań, zwiększać ich wydajność i wdrażać rozwiązania oparte na technice RAG.
-
książka
-
ebook
(71,40 zł najniższa cena z 30 dni)
71.40 zł
119.00 zł (-40%) -
-
 W tej niezwykle pragmatycznej książce, przeznaczonej dla dyrektorów technicznych, praktyków uczenia maszynowego, twórców aplikacji, analityków biznesowych, inżynierów i badaczy danych, znajdziesz skuteczne techniki używania sztucznej inteligencji. Zaznajomisz się z cyklem życia projektu opartego na generatywnej AI i jej zastosowaniami, a także metodami doboru i dostrajania modeli, generowania danych wspomaganego wyszukiwaniem, uczenia przez wzmacnianie na podstawie informacji zwrotnych od człowieka, kwantyzacji, optymalizacji i wdrażania modeli. Poznasz szczegóły różnych typów modeli, między innymi dużych językowych (LLM), multimodalnych generujących obrazy (Stable Diffusion) i odpowiadających na pytania wizualne (Flamingo/IDEFICS).
-
książka
-
ebook
(23,90 zł najniższa cena z 30 dni)
23.90 zł
79.00 zł (-70%) -
-
 Wprowadzenie obserwowalności do systemów jest wyzwaniem technicznym i kulturowym. Dzięki tej praktycznej książce zrozumiesz wartość obserwowalnych systemów i nauczysz się praktykować programowanie sterowane obserwowalnością. Przekonasz się, że dzięki jej wdrożeniu zespoły mogą szybko i bez obaw dostarczać kod, identyfikować wartości odstające i nietypowe zachowania, a ponadto lepiej zrozumieją doświadczenia użytkownika. Znajdziesz tu szczegółowe wyjaśnienia, co jest potrzebne do uzyskania wysokiej obserwowalności, a także szereg wskazówek, jak ulepszyć istniejące rozwiązania i pomyślnie dokonać migracji ze starszych narzędzi, takich jak wskaźniki, monitorowanie i zarządzanie dziennikami. Dowiesz się również, jaki wpływ ma obserwowalność systemu na kulturę organizacji ― i odwrotnie.
-
książka
-
ebook
(20,90 zł najniższa cena z 30 dni)
20.90 zł
69.00 zł (-70%) -
-
 Dzięki tej książce poznasz od podstaw Gita i GitLaba. Dowiesz się, jak skonfigurować runnery GitLaba, a także jak tworzyć i konfigurować potoki dla różnych etapów cyklu rozwoju oprogramowania. Poznasz zasady interpretacji wyników potoków w GitLabie. Nauczysz się też wdrażania kodu w różnych środowiskach i korzystania z wielu zaawansowanych funkcji, takich jak łączenie GitLaba z Terraformem, klastrami Kubernetes czy uruchamianie i poprawa wydajności potoków. Skorzystasz ponadto z licznych przykładów i studiów przypadków, dzięki którym za pomocą potoków CI/CD zautomatyzujesz wszystkie etapy DevOps do budowy i wdrażania kodu o wysokiej jakości.
-
książka
-
ebook
(23,90 zł najniższa cena z 30 dni)
23.90 zł
79.00 zł (-70%) -
-
 Oto przewodnik po inżynierii detekcji, przeznaczony dla inżynierów zabezpieczeń i analityków bezpieczeństwa. Zaprezentowano w nim praktyczną metodologię planowania, budowy i walidacji mechanizmów wykrywania zagrożeń. Opisano zasady pracy z frameworkami służącymi do testowania i uwierzytelniania programu inżynierii detekcji. Książka zawiera przykłady dotyczące zagadnień z całego cyklu, od utworzenia reguły detekcji po jej walidację, a omawianej tematyce towarzyszy bogaty zestaw samouczków, projektów i pytań sprawdzających. To doskonałe źródło wiedzy o zasadach pracy inżyniera detekcji i o ciągłym rozwoju tej dziedziny.
-
książka
-
ebook
(26,90 zł najniższa cena z 30 dni)
26.90 zł
89.00 zł (-70%) -
-
 Dzięki tej książce dowiesz się, jak tworzyć niezawodne, skalowalne i odporne rozwiązania, a także jak projektować systemy następnej generacji przeznaczone dla środowiska chmury. Poznasz efektywne strategie dla produktu i nauczysz się je w pełni implementować w swojej organizacji. Zrozumiesz też, w jaki sposób architekt rozwiązań wpisuje się w środowisko elastycznie działającej firmy. W tym wydaniu pojawiły się również nowe rozdziały, poświęcone takim technologiom jak internet rzeczy, obliczenia kwantowe, inżynieria danych i uczenie maszynowe. Znajdziesz tu uaktualnione informacje dotyczące architektury natywnej chmury i magazynu danych łańcucha bloków. W efekcie lektury nauczysz się tworzyć projekty efektywnych rozwiązań, spełniających zdefiniowane wymagania biznesowe.
-
książka
-
ebook
(38,90 zł najniższa cena z 30 dni)
38.90 zł
129.00 zł (-70%) -
-
 Autorzy, Joe Reis i Matt Housley, przeprowadzą Cię przez cykl życia inżynierii danych i pokażą, jak połączyć różne technologie chmurowe, aby spełnić potrzeby konsumentów danych w dolnej części strumienia przetwarzania. Dzięki lekturze tej książki dowiesz się, jak zastosować koncepcje generowania, pozyskiwania, orkiestracji, przekształcania, przechowywania i zarządzania danymi — kluczowe w każdym środowisku danych, niezależnie od wykorzystywanej technologii.
-
książka
-
ebook
(71,40 zł najniższa cena z 30 dni)
76.16 zł
119.00 zł (-36%) -
-
 To drugie, zaktualizowane i uzupełnione wydanie książki poświęconej wdrażaniu najlepszych praktyk DevOps przy użyciu nowoczesnych narzędzi. Przedstawiono w niej informacje o kulturze DevOps, opisano różne narzędzia i techniki stosowane do jej wdrażania, takie jak IaC, potoki Git i CI/CD, a także automatyzację testów i analizę kodu. Sporo miejsca poświęcono konteneryzacji aplikacji za pomocą Dockera i platformy Kubernetes. Znajdziemy tutaj również kwestię skracania przestojów podczas wdrażania oprogramowania i omówienie możliwości stosowania praktyk DevOps w projektach open source. Warto zwrócić uwagę na ostatni rozdział, w którym pokazano zasady wdrażania niektórych praktyk DevOps w całym cyklu życia projektów.
-
książka
-
ebook
(65,40 zł najniższa cena z 30 dni)
69.76 zł
109.00 zł (-36%) -

 Wybrane elementy graficzne tej sekcji powstały przy wsparciu AI
Szczegóły książki
- Tytuł oryginału:
- Serverless ETL and Analytics with AWS Glue. Design scalable data lakes, optimize ETL pipelines, and accelerate analytics on AWS - Second Edition
- ISBN Ebooka:
- 978-18-354-6801-2, 9781835468012
- Data wydania ebooka :
-
2026-08-28
 Data wydania ebooka często jest dniem wprowadzenia tytułu do sprzedaży i może nie być równoznaczna
z datą wydania książki papierowej. Dodatkowe informacje możesz znaleźć w darmowym fragmencie.
Jeśli masz wątpliwości skontaktuj się z nami sklep@helion.pl.
- Język publikacji:
- angielski
- Rozmiar pliku Pdf:
- 33.9MB
- Rozmiar pliku ePub:
- 15.5MB
Packt Publishing - inne książki
-
 Properly responding to an incident can mean the difference between a short or a catastrophic outage. In this book, cyber threat responders will be shown the tools, techniques and procedures necessary for an effective threat response.
-
-
ebook
(29,90 zł najniższa cena z 30 dni)
143.10 zł
159.00 zł (-10%) -
-
 The fourth edition of Microsoft Power BI Quick Start Guide helps you master data visualization and insights with ease, no experience needed. Learn Power BI fast and turn raw data into impactful decisions with hands-on, real-world examples.
-
-
ebook
(29,90 zł najniższa cena z 30 dni)
125.10 zł
139.00 zł (-10%) -
-
 Master the realm of Cyber Threat Intelligence and Proactive Threat Hunting with 'Practical Threat Intelligence and Data-Driven Threat Hunting, 2nd edition'. This is your essential guide in the ever-evolving landscape of cyber threats.
-
-
ebook
(29,90 zł najniższa cena z 30 dni)
116.10 zł
129.00 zł (-10%) -
-
 This latest edition of Practical Hardware Pentesting features even more practical advice on how to pentest various devices, from IoT to simpler hardware. As you progress through the chapters, you'll quickly learn the most common attack techniques, as well as ways to secure embedded systems and build more secure devices.
-
-
ebook
(29,90 zł najniższa cena z 30 dni)
125.10 zł
139.00 zł (-10%) -
Dzięki opcji "Druk na żądanie" do sprzedaży wracają tytuły Grupy Helion, które cieszyły sie dużym zainteresowaniem, a których nakład został wyprzedany.
Dla naszych Czytelników wydrukowaliśmy dodatkową pulę egzemplarzy w technice druku cyfrowego.
Co powinieneś wiedzieć o usłudze "Druk na żądanie":
- usługa obejmuje tylko widoczną poniżej listę tytułów, którą na bieżąco aktualizujemy;
- cena książki może być wyższa od początkowej ceny detalicznej, co jest spowodowane kosztami druku cyfrowego (wyższymi niż koszty tradycyjnego druku offsetowego). Obowiązująca cena jest zawsze podawana na stronie WWW książki;
- zawartość książki wraz z dodatkami (płyta CD, DVD) odpowiada jej pierwotnemu wydaniu i jest w pełni komplementarna;
- usługa nie obejmuje książek w kolorze.
Masz pytanie o konkretny tytuł? Napisz do nas: sklep@helion.pl
Książka drukowana

Oceny i opinie klientów: Serverless ETL and Analytics with AWS Glue. Design scalable data lakes, optimize ETL pipelines, and accelerate analytics on AWS - Second Edition Noritaka Sekiyama, Albert Quiroga, Tomohiro Tanaka, Subramanya Vajiraya, Akira Ajisaka, Ishan Gaur
(0)